Terminal coding agents have become very good at reading and changing code. Claude Code, Codex, Gemini CLI and OpenCode can search a repository, follow imports and make careful edits across files. What none of them do on their own is look at the page. They work on text, and a UI bug is something you see.
A growing set of tools tries to close that gap. They don't all do the same thing, and picking the right one depends on who should be driving: you or the agent. This post sorts them by how they work. We build one of them, PulseDev, so take our view of it with that in mind. The descriptions of other tools reflect what their own docs and repositories say as of October 2026; check them before you decide, because this area changes quickly.
Why can't coding agents see your UI?
A terminal agent sees your files, the output of commands it runs, and whatever you paste into the conversation. The rendered page lives in a browser process it has no connection to. It can read PricingCard.tsx and reason about what it probably renders, but it can't know that the button wraps onto two lines at 1180px, or that a global rule from a library is overriding your padding.
So the question every tool in this list answers is: how does information about the rendered page get to the agent? There are roughly four answers.
What are the main ways to give an agent browser context?
1. Paste a screenshot
The simplest option, and built in. Claude Code and most other agents accept images, so you can take a screenshot and add it to your message. Models are decent at reading layout from an image.
The catch is that a screenshot shows the problem but not its cause. The agent still has to work out which component and which rule produced what it sees, and it does that by guessing from the picture and searching your code. For one-off issues that's often fine. For a list of small fixes, the copying and describing adds up.
2. Let the agent drive a browser
Browser automation servers give the agent tools to open pages and inspect them itself. Two widely used ones are Playwright MCP from Microsoft and Chrome DevTools MCP from the Chrome team.
Playwright MCP works mainly from the page's accessibility tree rather than pixels, so the agent gets structured text about what's on the page and can click, type and navigate. Chrome DevTools MCP lets an agent control a live Chrome instance: take screenshots, read console messages, inspect network requests and record performance traces.
This approach is strong when the agent needs to reproduce something on its own, like walking through a checkout flow to see where it breaks, or checking the console after a change. It's less direct when you already know which element is wrong. You end up describing it in words so the agent can find it in a page it's looking at separately from you.
3. Pick an element and copy its context
Element pickers run in your page during development. You hover or click an element, and the tool copies context about it for you to paste into your agent. React Grab is a well-known example for React apps: you hover an element, press Cmd+C, and it copies the element along with its component stack and source locations.
Because it reads React's internals, the context is precise: you get the component and the file, not just a selector. The trade-off is scope. It's built around React, and you still carry the context to the agent yourself.
4. Point at the element and send the task to your agent
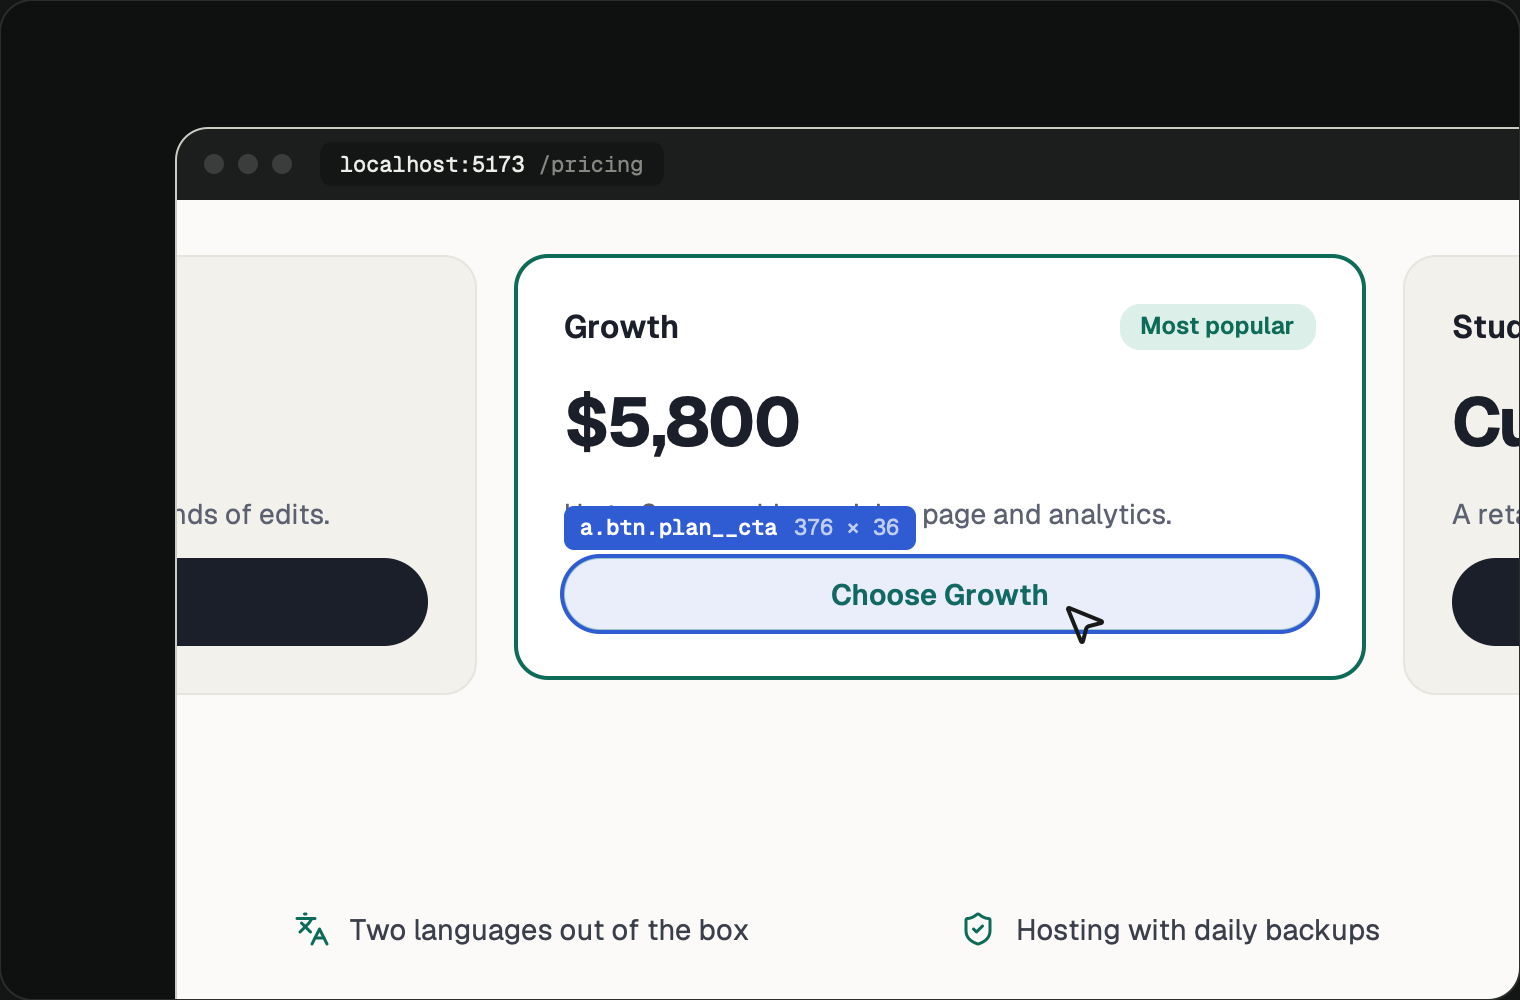
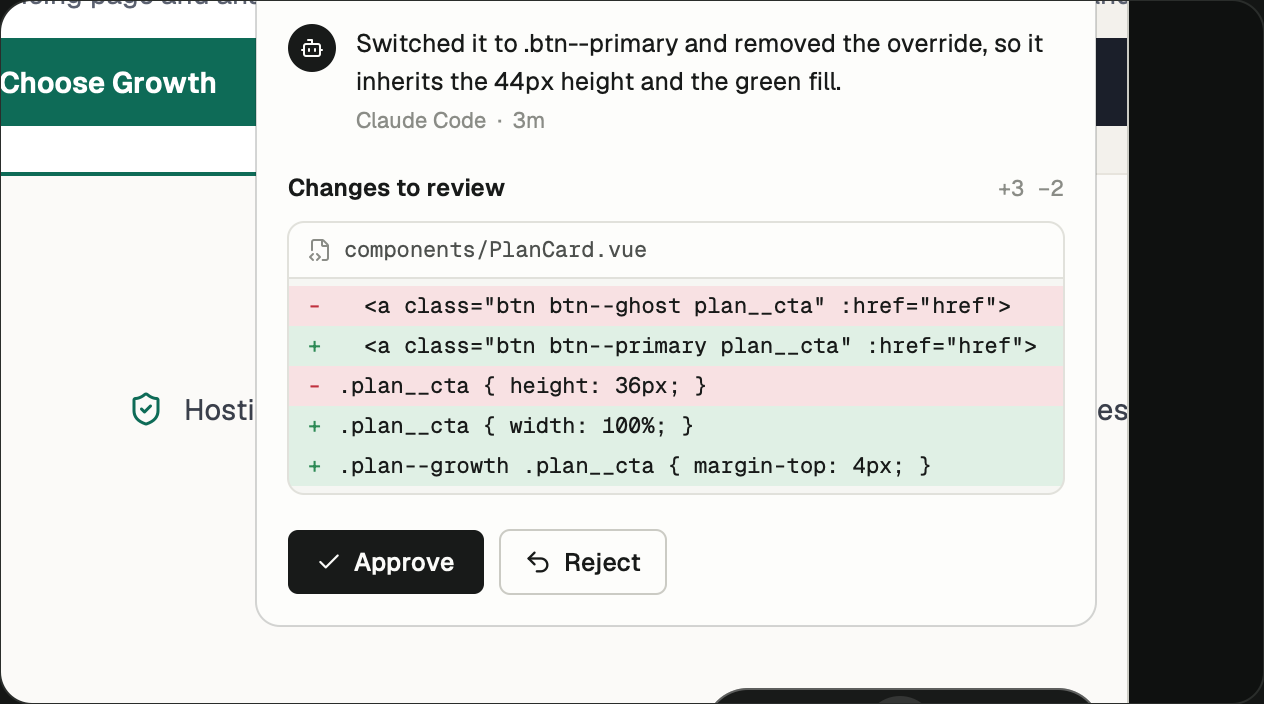
This is the category PulseDev is in. A small script on your dev page adds a button. You click the element, type the fix, and the tool runs your coding agent in your project with the element's context attached. The result comes back as a diff in the page, and you approve or reject it.
In PulseDev's case the context is DOM-level: the selector, page URL, markup, computed styles, matched CSS rules, recent console errors and an element screenshot. It runs Claude Code, Codex or Gemini CLI, using whichever you've installed and signed in to. Because it works from the rendered DOM, it doesn't depend on the framework. The same script tag works on React, Vue, Svelte, Astro, Laravel, Hugo or plain HTML. The flip side is that it doesn't yet read component trees, so on markup-heavy pages the agent relies on classes, text and your note to find the right file. It's also macOS only for now.
A fifth option: an editor or browser with the agent built in
Some products combine the browser and the agent in one app. Stagewise, for example, now describes itself as an open-source agentic IDE that pairs browsing with a built-in coding agent and its own choice of model providers. Editors like Cursor have also added ways to preview and select UI. These suit you if you're happy to move your workflow into that tool. If you want to keep using a terminal agent you already pay for, the other categories fit better.
How do these approaches compare?
| Approach | Who finds the element | What the agent gets | Framework limits |
|---|---|---|---|
| Pasted screenshot | You, by describing it | An image | None |
| Browser automation MCP | The agent, by navigating | Accessibility tree or screenshots, console, network | None |
| Element picker (e.g. React Grab) | You, by clicking | Element plus component stack and source location | React |
| Point and send (e.g. PulseDev) | You, by clicking | Selector, markup, styles, matched rules, console, screenshot | None; macOS app |
| Agentic browser or IDE | Either | Depends on the product | Depends on the product |
Which one should you use?
Start from the job, not the tool:
- You need the agent to reproduce or test something by itself. Use a browser automation MCP server. Letting the agent click through a flow and read the console is what they're designed for.
- You're on React and want exact source locations. An element picker like React Grab gives the agent the component and file directly.
- You have a list of visual fixes and know exactly which elements are wrong. Pointing and sending is the shortest path: click, describe, review, next. That's the case PulseDev is built for, on any stack.
- It's a one-off and you're already in the terminal. Paste a screenshot.
Can you combine them?
Yes, and it's common. They solve different halves of the problem. A typical split is to point at elements for the fixes you can see, and give the agent a browser MCP server for checks it should run itself, like confirming there are no console errors after a change. PulseDev also exposes its own MCP server, so an agent in your editor can list the notes you left on the page and work through them in one session. See Connect your editor for how that's set up.
Whichever you choose, keep reviewing diffs. More context makes agents better at finding the right file. It doesn't make them better judges of your design than you are.